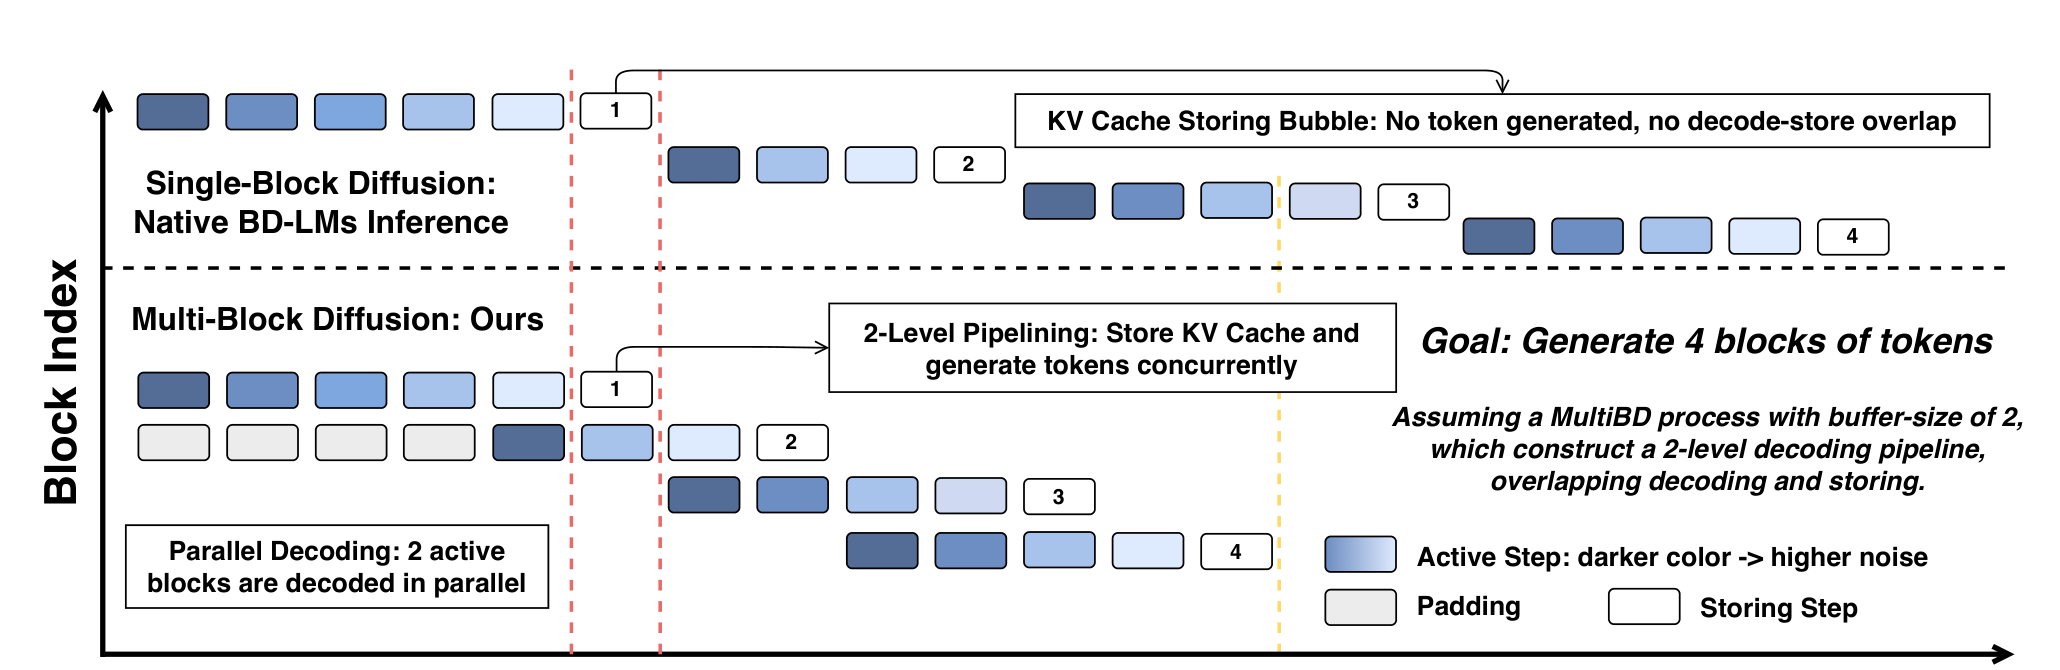
Multi-Block Diffusion Language Models
Multi-block Teacher Forcing and Block Buffer decoding enable concurrent refinement across diffusion language model blocks.
Ideas, methods, and stories behind our research.
Multi-block Teacher Forcing and Block Buffer decoding enable concurrent refinement across diffusion language model blocks.
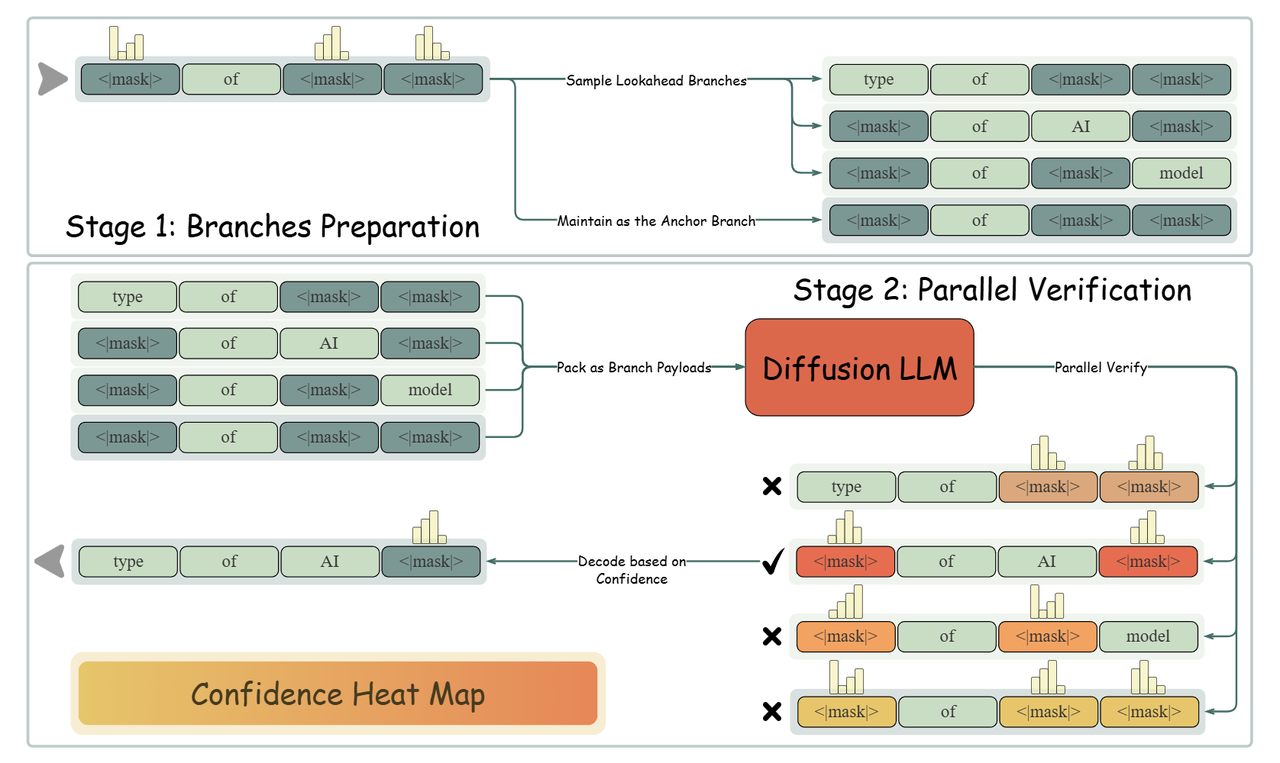
Lookahead Parallel Decoding enables diffusion language models to generate up to 10.1 tokens per forward pass.
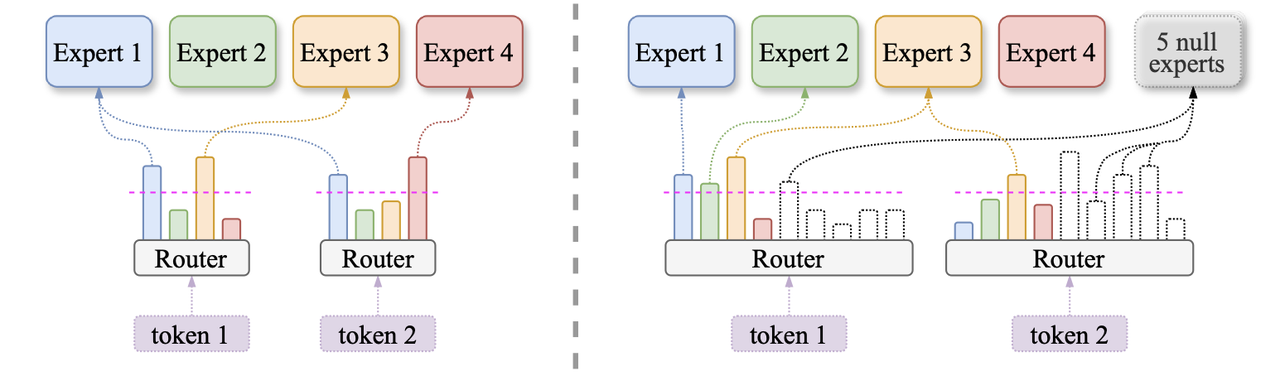
Null experts let each token activate a different number of real experts, reducing computation while preserving accuracy.
通过引入零计算开销的“空专家”,让每个 Token 自适应选择真实专家数量,在降低计算量的同时保持模型表现。
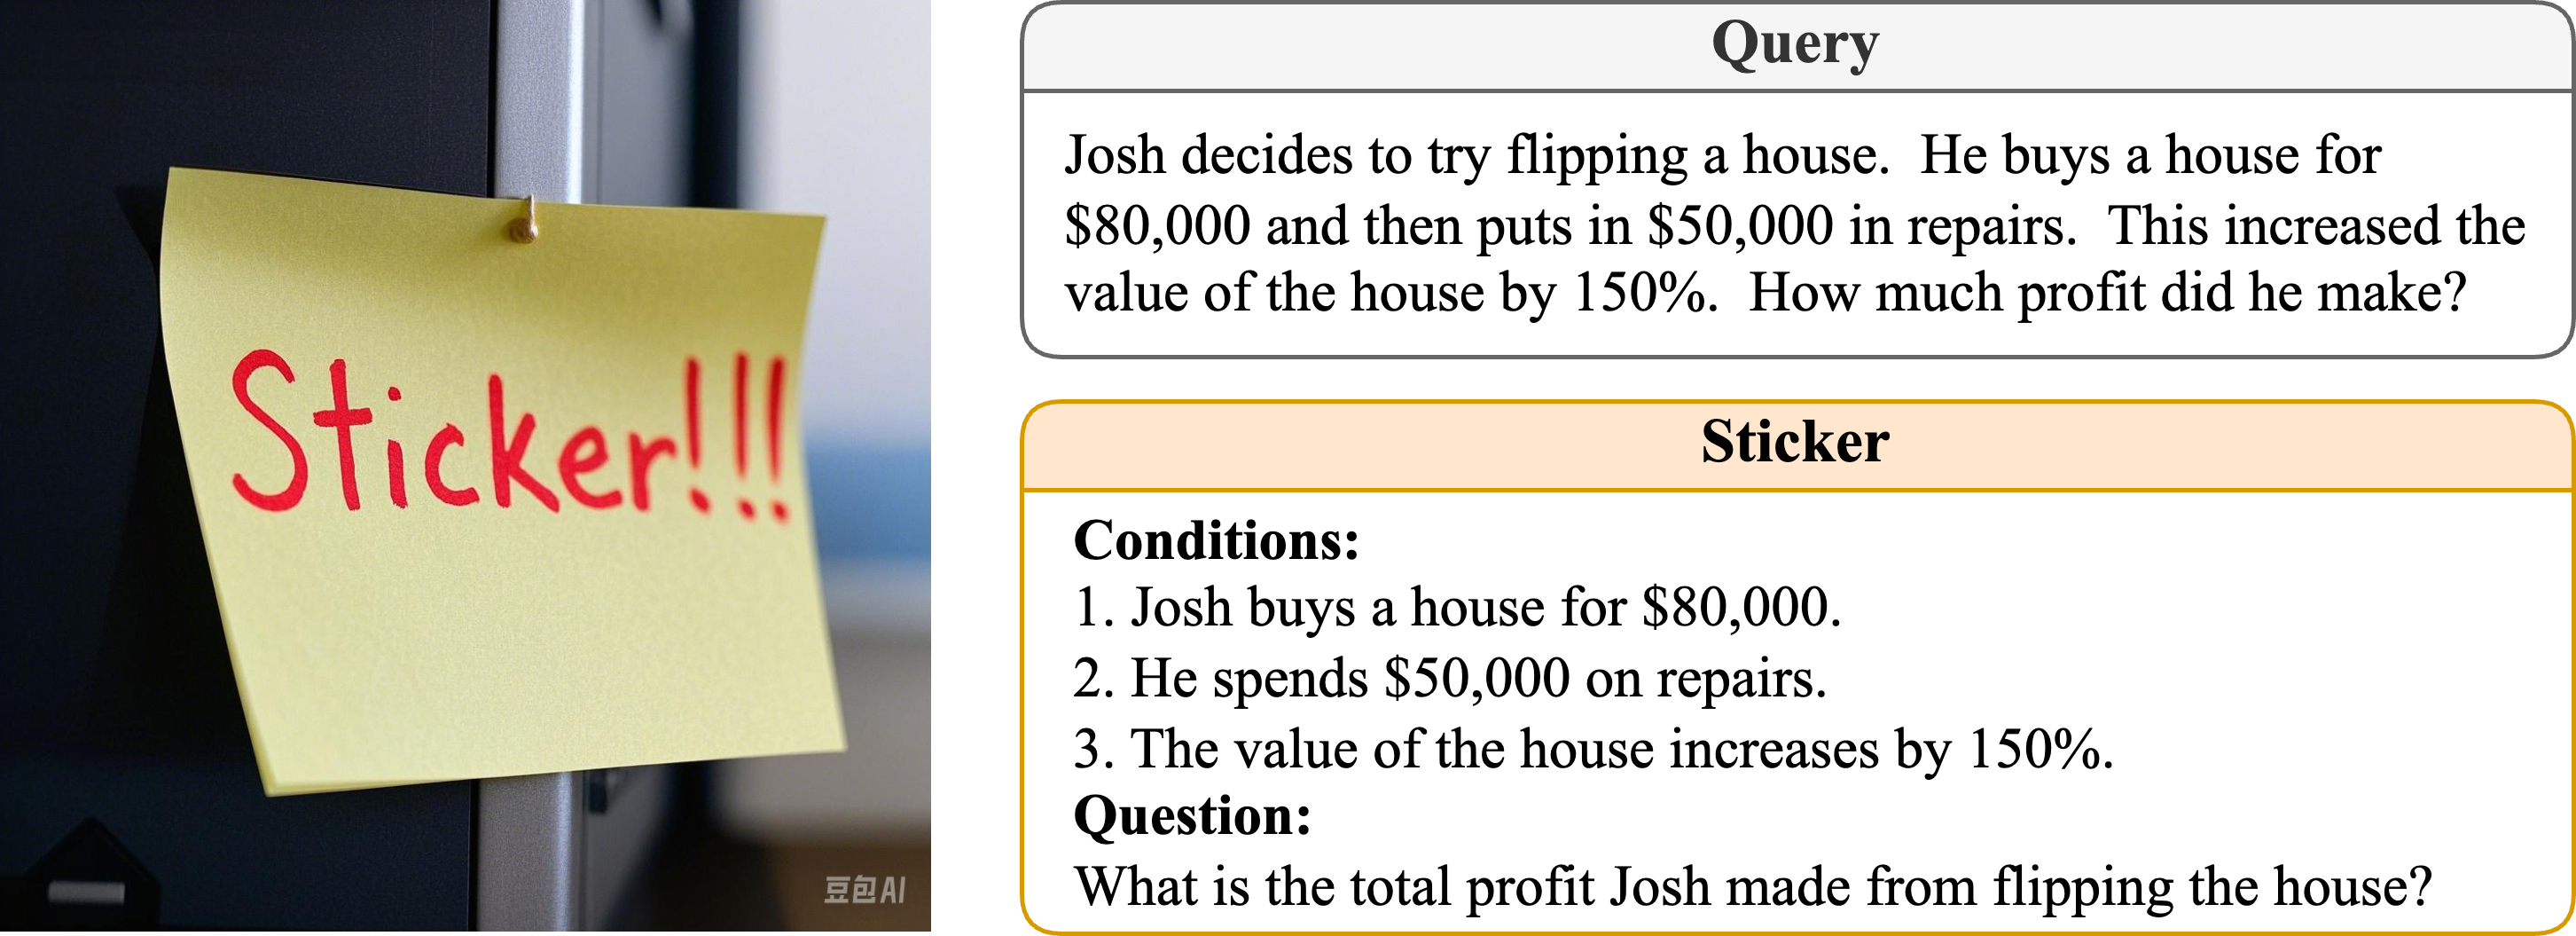
Dynamically generated Stickers summarize key facts and constraints to keep language model reasoning grounded in the query.
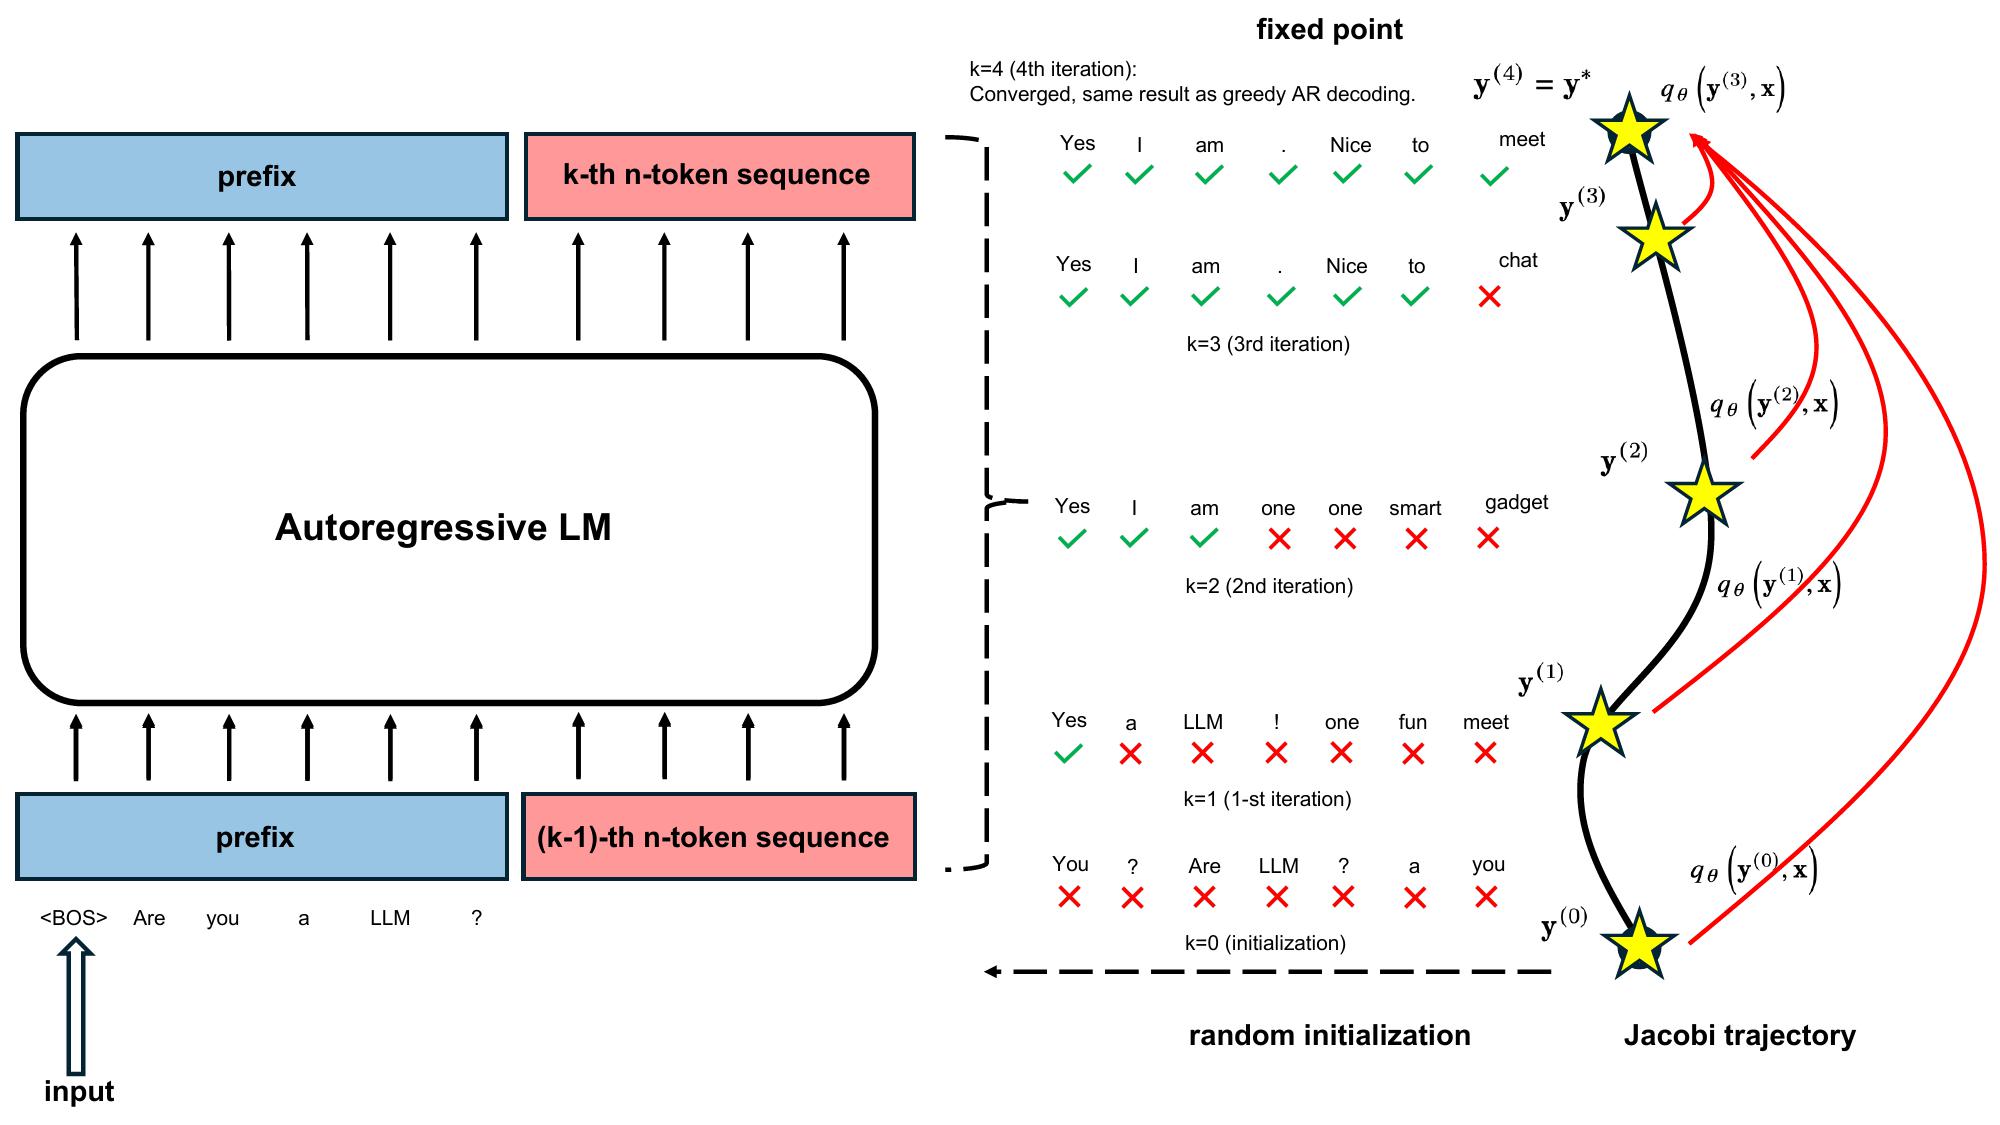
Consistency training teaches pretrained language models to decode multiple tokens in parallel without additional inference-time model components.