
 Promo video
TL;DR
Multi-step streaming video, one chunk per forward round.
Wave Forcing (WF) co-designs generation, training and execution. A causal wavefront lets newer, noisier chunks read earlier, cleaner ones, so denoising stages run concurrently on full-model replicas. Wave Runtime (WaveRT) hides K/V delivery behind compute and pipelines VAE decoding.
‡ The 1.3B rows use the released 4-step and 5-step checkpoints. Timings for scales above 1.3B use randomly initialized (dummy) DiT weights with a real-weight VAE, because pretrained weights at those scales are unavailable and the 14B scale could not be adequately trained. FPS is 1593 decoded frames divided by the median of three runs.
Abstract
Real-time long-video generation requires continuous output with consistent appearance and natural motion. Existing chunk-wise autoregressive methods face challenges in both generation efficiency and long-video quality: serialized denoising and history-cache refresh require two forward passes even with one-step denoising, and longer rollouts can degrade quality and cause camera drift. We propose Wave Forcing (WF), which co-designs generation, training, and execution for continuous video output with multi-step denoising. WF uses chunk-wise causal attention to access earlier, cleaner chunks before their denoising is complete, and distributes staggered denoising and cache-refresh stages across full-model replicas to achieve 1F1C: one output chunk per concurrent forward round after pipeline fill. To adapt the model to this continuous generation process, we develop a three-stage training procedure that successively introduces mixed-noise denoising, motion supervision, and causal adaptation using self-generated history. To execute this process efficiently, Wave Runtime (WaveRT) uses Wave Parallelism (WP) for early K/V delivery and communication–computation overlap, together with optimized kernels and pipelined VAE decoding.
Experiments on Wan2.1-T2V-1.3B show that 5-step WF maintains overall quality comparable to Rolling Forcing while achieving higher Dynamic Degree on both short and long videos. Our system efficiency experiments show that 4-step WF achieves 147.6 DiT FPS and 134.8 end-to-end FPS on eight H200 GPUs, yielding 7.07× the single-GPU end-to-end throughput. In DiT-only tests with matched SageAttention+W8A8 backends, denoising steps, and GPU counts, WP delivers up to 2.53× the throughput of the faster of the Ulysses and Ring context-parallel baselines across six model scales (1.3B–14B).
Method · Wave Forcing
A bounded-width causal wavefront.
Earlier chunks run later denoising stages while newer chunks run earlier ones. Each denoising stage and the store pass own a full-model replica, so the staggered tasks advance together as a moving wavefront.
N forward rounds per chunk
Chunk-wise autoregressive methods such as Self Forcing and Causal Forcing denoise each chunk on top of earlier content, then run one more forward pass, the store, to refresh the K/V history from the clean result. Denoising and store sit between consecutive outputs, so even one-step denoising needs two forward passes per chunk.
One chunk per concurrent forward round
WF keeps every denoising update but staggers them: with S denoising stages plus store on S + 1 replicas, one completed chunk leaves the pipeline per round after fill. Chunk-wise causal attention keeps full attention within a chunk; across time, query slot s reads K/V slot j only if j ≥ s, which means itself and all cleaner predecessors, never a later chunk.
Wavefront explorer S = 4
Chunk-wise causal mask M(s, j) = 1[j ≥ s]
Rows: query slot s (chunk i = k − s). Columns: K/V slot j. Every slot also reads the anchor, clean history and live store.
scroll sideways →
Method · Training
Training for the deployment graph.
The causal mask removes access to later, noisier chunks and changes the conditioning Rolling Forcing learned. Three stages adapt Wan2.1-T2V-1.3B to it.
Mixed-noise initialization
RF's mixed-noise joint-denoising setup, with bidirectional attention across chunks at different noise levels. Each step samples an RF or an SF rollout with equal probability and trains with DMD. SF rollouts help stabilize motion.
Off-policy DMD
Following LPM 1.0: consecutive teacher chunks are re-noised at staggered timesteps, with earlier teacher chunks as clean K/V history. DMD and LPIPS supervise the same prediction, adding stronger motion and subject guidance.
Causal adaptation, self-generated history
Each iteration uniformly samples a self-generated RF, WF or SF rollout for on-policy DMD. The WF branch uses the causal context, including store-refreshed history from its own outputs.
The 4-step student starts from SF's ODE initialization. The 5-step student reuses the released RF weights and skips Stage 1.
System · Wave Runtime
Wave Parallelism hides K/V delivery behind compute.
WF exposes stage concurrency, but K/V dependencies can still stall attention. WaveRT, built on SGLang Diffusion's model implementation, publishes K/V early from stage-owned replicas and overlaps delivery with computation when cleaner producers run ahead.
Stage-owned replicas
Each denoising stage and the store own a full-model GPU replica. Rank s updates chunk k − s and hands it to rank s + 1 for the next round.
Early publication
Cleaner ranks read fewer keys, so they can run ahead. K/V is published after QKV + RoPE, and readiness is checked just before attention.
we = max(0, τe − Δe)Paged delivery
K/V is written directly into ordered attention slots and signalled ready before use, with no remote concatenation. Attention consumes the same K/V values as synchronized execution.
Kernels + pipelined VAE
SageAttention and W8A8 speed up local operators. The VAE decoder is split into profile-balanced contiguous stages on dedicated GPUs, overlapping DiT.
Wave Parallelism · inside one round
K/V ships while compute runs
scroll sideways →
Bars are measured tick p50 for 1.3B BF16 (4-step, 8 GPUs); each one adds a mechanism to the one above, and Early publish is the Overlap column. Block widths in the diagram are schematic.‡
Paper figure: K/V delivery schedules
scroll sideways →
VAE pipeline parallelism
Three decode stages, each about one round long
scroll sideways →
8×H200: four GPUs denoise, one runs the store pass, three decode. The round and the stage times are measured; the two shorter FLOP-split stages are not reported, so their widths are schematic. End to end the runtime reaches 134.8 FPS against 147.6 DiT FPS, and the first output still pays the pipeline-fill latency.‡
Paper figure: streaming VAE schedules
scroll sideways →
Results · Efficiency
147.6 DiT FPS, 134.8 end to end.
4-step WaveRT at 832×480 on one 8×H200 node: four GPUs denoise, one runs store, and three decode as a load-balanced VAE pipeline.
The 1.3B rows use the released 4-step and 5-step checkpoints. The 14B rows use randomly initialized (dummy) DiT weights, because pretrained weights are unavailable at that scale and there was not enough compute to adequately train it; the VAE uses real weights. FPS is 1593 decoded frames divided by the median elapsed time over three runs; loading and file encoding are excluded.
| Configuration | GPUs | Tick p50 (ms) | Steady (FPS) | DiT (FPS) | E2E (FPS) | Speedup |
|---|---|---|---|---|---|---|
| 1.3B, 4-step | ||||||
| Baseline | 1 | – | – | 33.86 | 19.06 | 1.00× |
| WaveRT (Sync) | 8 | 91.96 | 130.50 | 129.31 | 127.06 | 6.67× |
| WaveRT | 8 | 78.88 | 152.13 | 147.58 | 134.81 | 7.07× |
| WaveRT + Sage | 8 | 78.36 | 153.15 | 147.78 | 134.79 | 7.07× |
| WaveRT + Sage + W8A8 | 8 | 76.05 | 157.79 | 145.47 | 132.89 | 6.97× |
| 1.3B, 5-step | ||||||
| Baseline | 1 | – | – | 29.12 | 17.46 | 1.00× |
| WaveRT | 8 | 120.53 | 99.56 | 104.82 | 96.46 | 5.52× |
| WaveRT + Sage | 8 | 120.52 | 99.57 | 104.80 | 96.48 | 5.53× |
| WaveRT + Sage + W8A8 | 8 | 120.59 | 99.51 | 103.49 | 95.15 | 5.45× |
| 14B, 4-step† | ||||||
| Baseline | 1 | – | – | 6.31 | 5.51 | 1.00× |
| WaveRT (Sync) | 8 | 464.27 | 25.85 | 25.56 | 25.47 | 4.62× |
| WaveRT | 8 | 413.80 | 29.00 | 28.74 | 28.64 | 5.20× |
| WaveRT + Sage | 8 | 414.03 | 28.98 | 28.72 | 28.62 | 5.19× |
| WaveRT + Sage + W8A8 | 8 | 354.45 | 33.86 | 33.64 | 33.50 | 6.08× |
Wave Parallelism vs context parallelism
DiT-only throughput (dummy weights, VAE disabled) against attention-level context parallelism, Ulysses and Ring, across six model scales. Steps and GPUs are matched within each row: 5 steps on 6 GPUs for 1.3B–9B, 4 steps on 5 GPUs for 14B. Under Sage+W8A8, WP comes first at every scale, at 1.025–2.530× the faster CP. Under BF16 it leads at five of six scales (0.985–1.862×); at 9B it trails Ulysses by 1.53%.
DiT throughput (FPS) by model scale
Sage+W8A8 · higher is better
† supplemental measurements with a target-stopped repetition protocol (see the paper's appendix).
| Scale | Compute | Steps | GPUs | Ulysses CP | Ring CP | WP | WP/CP |
|---|
K/V transport ablation
Same model, WF graph, schedule, topology and local compute per row; only the execution strategy changes. Sync gathers layer K/V before attention; Overlap publishes it early; One-sided uses CUDA IPC P2P; Staggered prefetches readiness checks; Paged writes directly into final attention-buffer slots. Sync → Paged lowers BF16 tick p50 by 14.2% at 1.3B and 10.9% at 14B.
| Backbone | Compute | Sync | Overlap | One-sided | Staggered | Paged |
|---|---|---|---|---|---|---|
| 1.3B | BF16 | 91.956 | 85.730 | 81.669 | 81.953 | 78.882 |
| 1.3B | Sage | 91.441 | 84.103 | 80.934 | 81.062 | 78.356 |
| 1.3B | Sage+W8A8 | 88.714 | 81.595 | 78.030 | 78.081 | 76.052 |
| 14B | BF16 | 464.270 | 449.689 | 425.907 | 425.188 | 413.795 |
| 14B | Sage | 467.526 | 439.988 | 426.215 | 425.601 | 414.029 |
| 14B | Sage+W8A8 | 407.215 | 379.576 | 365.922 | 366.697 | 354.447 |
Results · Quality
Quality holds, and the video moves.
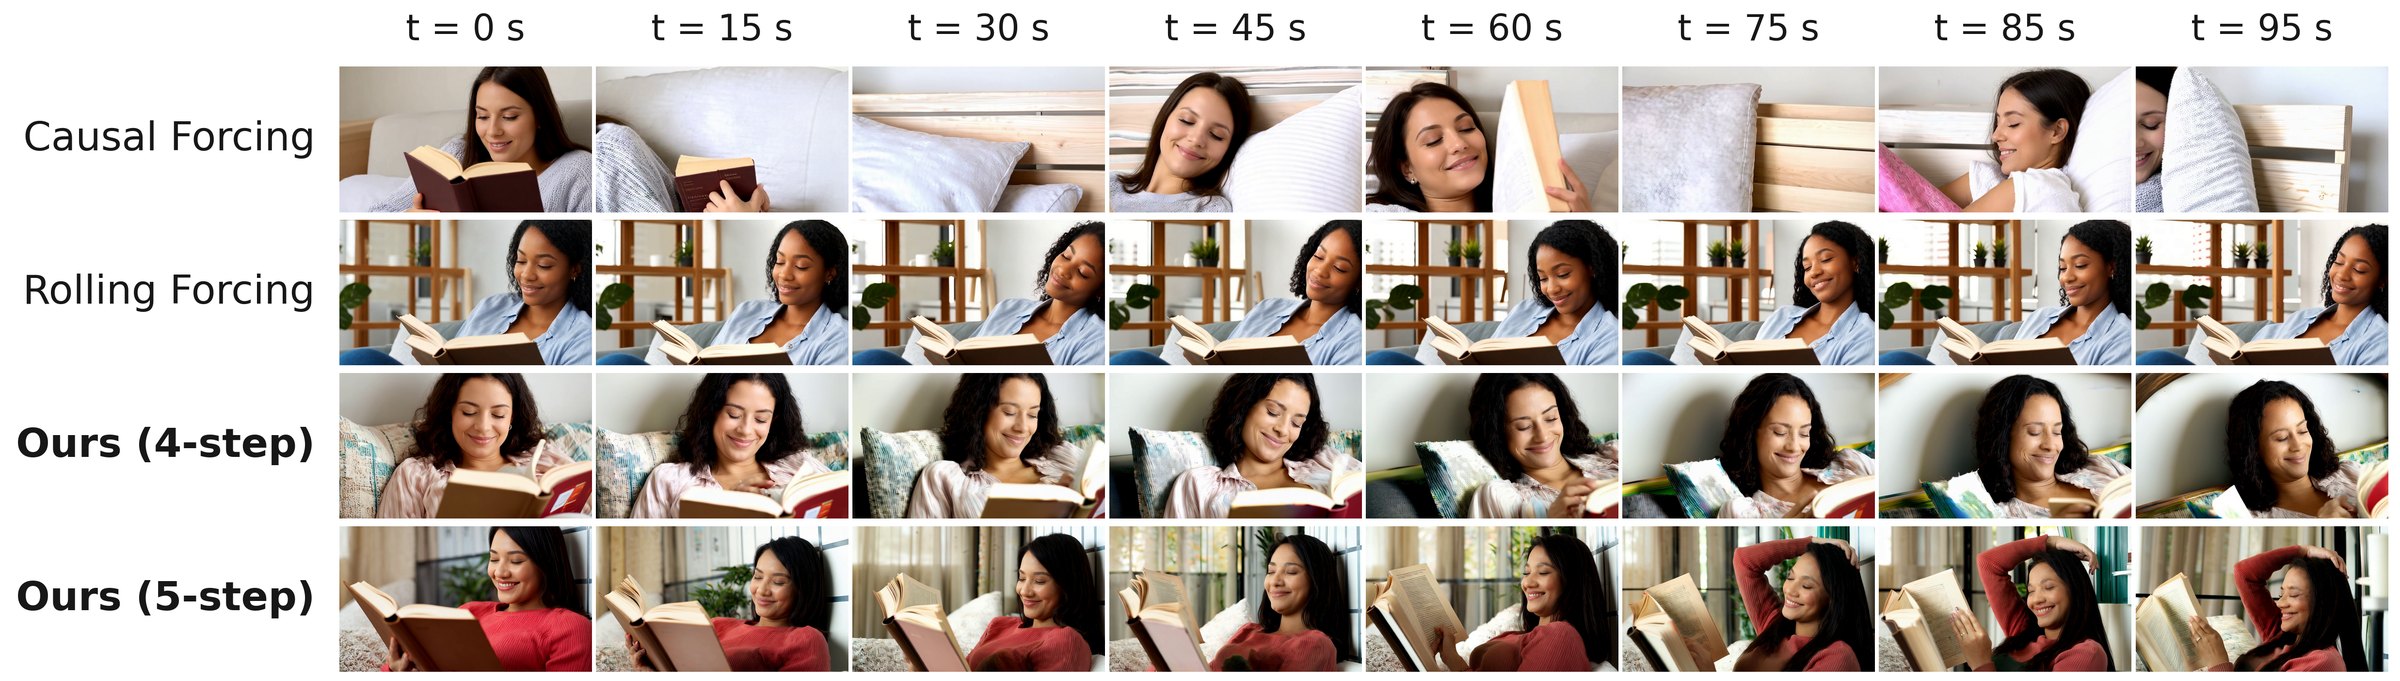
5-step WF matches Rolling Forcing's overall quality while lifting Dynamic Degree on both short and 100-second videos, with no unusable score on any metric.
| Standard VBench ↑ | VBench-Long ↑ | Stability | FPS ↑ | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Method | Steps | GPUs | Total | Quality | Semantic | Dynamic | Quality | Dynamic | Subj. ↑ | Drift ↓ | DiT | E2E |
| Rolling Forcing | 5 | 1 | 81.15 | 83.77 | 70.66 | 51.39 | 81.18 | 36.63 | 92.75 | 0.17 | 29.12 | 17.46 |
| + Causal Attention | 5 | 8 | 80.89 | 83.35 | 71.05 | 37.50 | 80.50 | 46.60 | 91.26 | 0.40 | 104.85 | 96.56 |
| Causal Forcing (Full Attn.) | 4 | 1 | 79.61 | 82.83 | 66.72 | 100.00 | 82.15 | 96.61 | 71.11 | 11.14 | 33.88 | 19.06 |
| Wave Forcing (Ours) | 4 | 8 | 80.74 | 83.93 | 67.95 | 84.72 | 80.89 | 74.97 | 91.88 | 0.36 | 147.58 | 134.81 |
| + SageAttention | 8 | 81.03 | 84.02 | 69.07 | 65.28 | 81.16 | 77.24 | 90.79 | 0.36 | 147.78 | 134.79 | |
| Wave Forcing (Ours) | 5 | 8 | 81.64 | 84.40 | 70.59 | 94.44 | 81.26 | 91.45 | 97.10 | 0.37 | 104.82 | 96.46 |
| + SageAttention | 8 | 81.02 | 83.92 | 69.41 | 80.56 | 81.14 | 91.14 | 94.43 | 0.37 | 104.80 | 96.48 | |
Training ablations
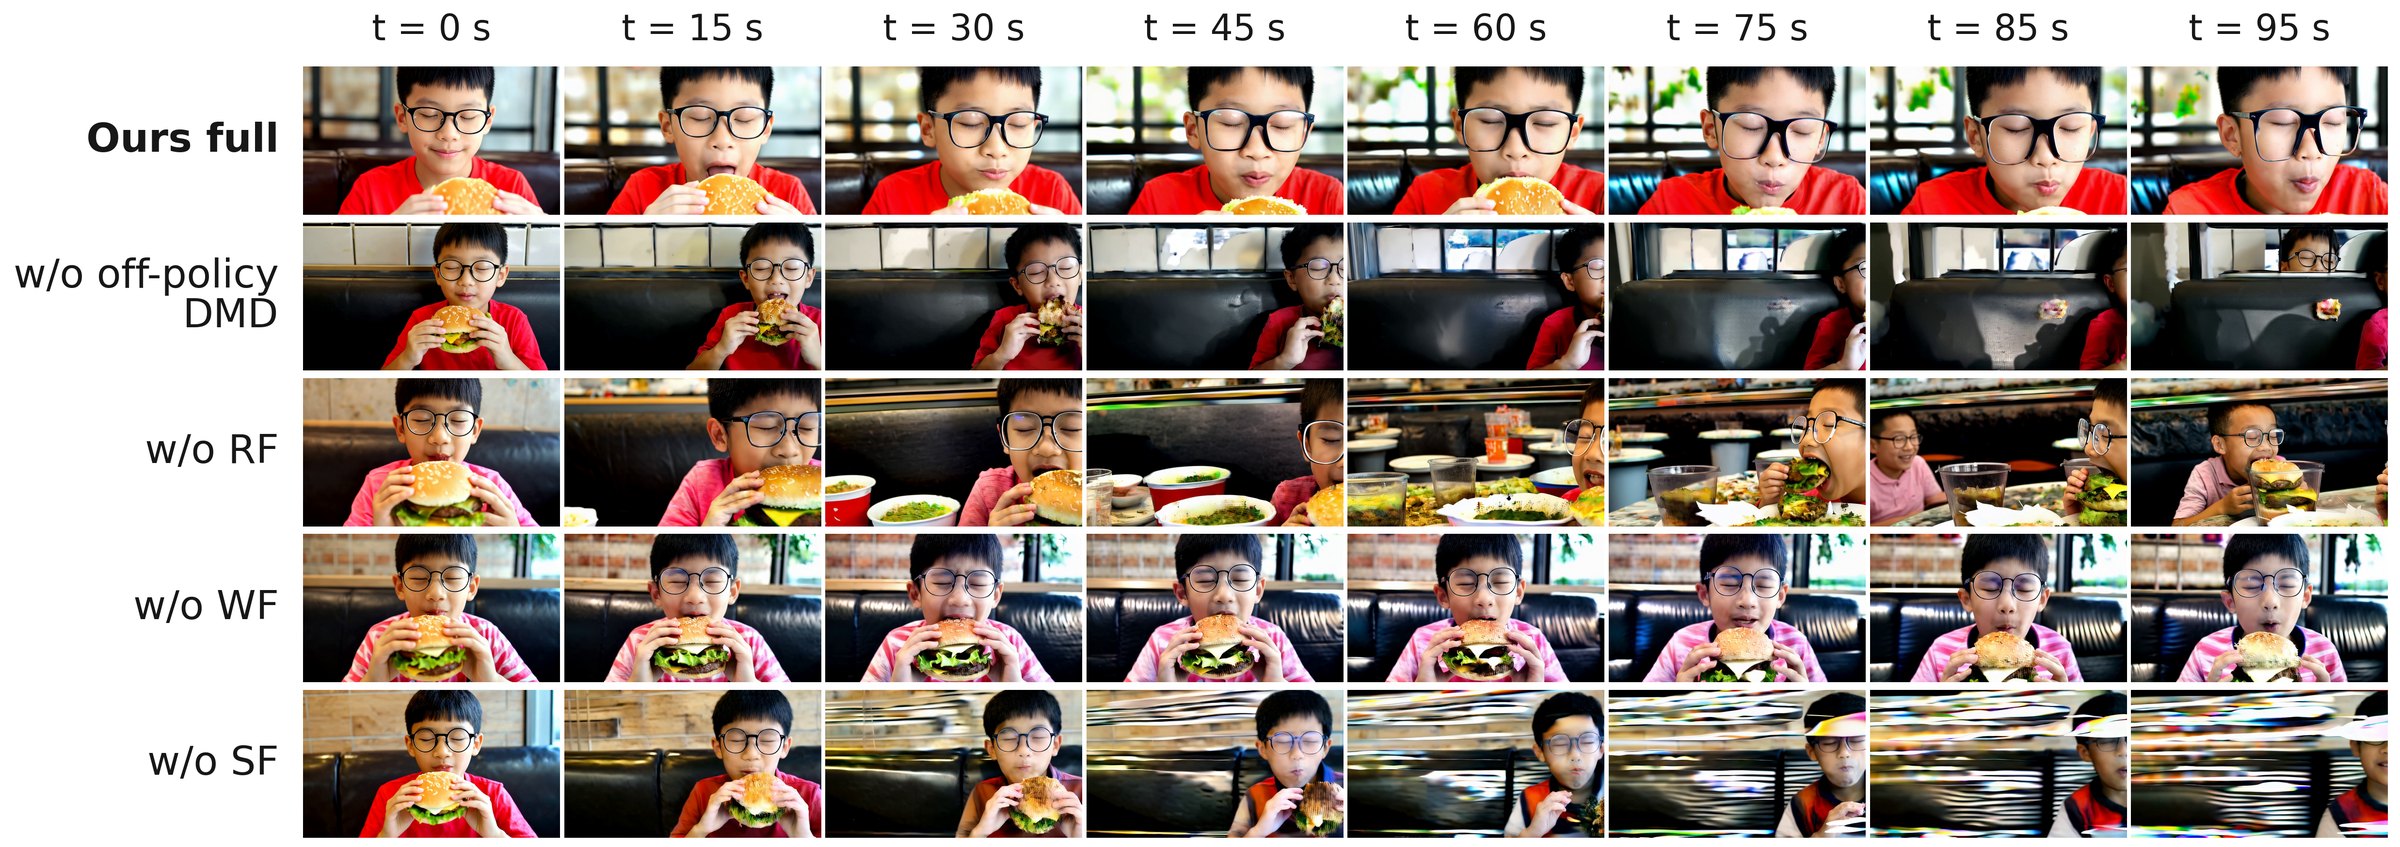
4-step models on long videos. Skipping off-policy DMD collapses motion (Dynamic Degree 15.73) and loses the subject. Removing RF raises motion but destabilizes framing (Drift 6.24). Removing WF gives the steadiest camera but halves motion (48.12). Removing SF degrades quality. The full recipe is the only one with no unusable score.
| Model | Quality ↑ | Dynamic ↑ | Subj. ↑ | Drift ↓ |
|---|---|---|---|---|
| w/o off-policy DMD | 76.68 | 15.73 | 76.53 | 0.26 |
| w/o RF | 80.19 | 88.82 | 77.48 | 6.24 |
| w/o WF | 80.34 | 48.12 | 95.64 | 0.10 |
| w/o SF | 75.35 | 23.66 | 84.04 | 1.89 |
| Ours full | 80.89 | 74.97 | 91.88 | 0.36 |
Qualitative
Long rollouts that keep their subject.
One 60-second take
A single 5-step Wave Forcing rollout, played back unedited. Nothing is cut or stitched: every chunk is generated causally from the ones before it.

I'll just watch this one for a minute…
More generations
Downscaled previews; click a clip to play it. High-motion and 100 s sets: 5-step WaveForcing-1.3B, MovieGen prompts, seed 42, except the 10 s p054 (seed 123, the best of five). Each 100 s clip is one uncut 1593-frame rollout; p032, p287, p269 and p003 use seeds 1, 1, 1 and 123, each the best of three to eight seeds.
Rolling Forcing · 5-step
Wave Forcing · 5-step, same prompt
Same prompt, 100 s each. Over the rollout the Rolling Forcing listener changes identity (hair, glasses, face); Wave Forcing keeps both people.
Limitations
What's still open.
The VAE output path
Pipelining overlaps and partitions decoding but doesn't remove its finite capacity. The DiT/E2E gap (147.58 vs 134.81 FPS at 4 steps) is consistent with residual decoder and output-path limits; matched VAE-on/off runs are needed to isolate the bottleneck.
Training complexity
Simplifying mixed-noise initialization, teacher guidance and causal adaptation to self-generated history, while keeping motion and long-video stability, remains open.
Scalability
Pipeline width is bounded by the number of denoising steps, which limits how far one pipeline scales to more GPUs. WP's advantage over CP also narrows for larger models.
@misc{denglab2026waveforcing,
  title        = {Wave Forcing: Towards Speed-of-Light Streaming Video Generation},
  author       = {Jin, Yijie and Liu, Yuxuan and Xu, Jiajun and Huang, Ye and Wang, Chuzhi and
                  Li, Jiayang and Chen, Ruiyang and Hong, Chenling and Wang, Xu and Deng, Zhijie},
  year         = {2026},
  eprint       = {2611.00859},
  archivePrefix = {arXiv},
  url          = {https://arxiv.org/abs/2611.00859}
}